Category | DevOps
Last Updated On 10/08/2026
If you've typed "SRE Roadmap" into Google today, you already know the problem: a hundred tabs, a dozen conflicting diagrams, and no real sense of where to actually start. This guide fixes that. It's a single, structured SRE Roadmap that takes you from "I don't know what SRE is" to "I'm interviewing for SRE roles" with no fluff and no guesswork.
In a world where a five-minute outage can cost a company millions and a user's trust in seconds, Site Reliability Engineering has gone from a Google-only specialty to a global standard for how modern IT teams operate. This Site Reliability Engineering Roadmap covers everything: the foundational skills, the tools that actually show up in interviews, the certifications worth your money, realistic salary expectations, and how AI is changing the game in 2026.
Whether you're a fresh graduate, a sysadmin looking to level up, or a developer curious about reliability engineering, this roadmap will give you a clear, honest SRE Learning Path to follow.
Let's break it down simply. Site Reliability Engineering (SRE) is a discipline pioneered by Google to keep services reliable, scalable, and efficient. It applies the mindset and rigor of software engineering to problems that used to live entirely in operations. If you want a deeper dive into the core concepts before moving ahead, check out our guide on SRE Fundamentals.
SRE professionals don't just fix systems when they break; they design systems that are far less likely to break in the first place.
Here's what sets an SRE apart from a traditional ops role:
This is exactly why a structured SRE roadmap matters so much: it takes you from ad hoc troubleshooting knowledge to the ability to design and defend large-scale, resilient systems.
Search "SRE roadmap," and you'll find dozens of impressive-looking diagrams. Most of them are too generic to actually help you land a role or perform on the job. A real SRE Roadmap needs to do three things: sequence your learning correctly (so you're not learning Kubernetes before you understand Linux), map skills to what companies are actually hiring for, and account for how the role itself is shifting — especially with AI now embedded in monitoring, incident response, and capacity planning.
Reliability is no longer a "nice to have." As organizations run more of their business on cloud-native, distributed systems, the cost of downtime keeps climbing, and demand for engineers who can prevent it — not just react to it — keeps climbing with it. That's the entire premise behind this roadmap.
Before you go further into the SRE Roadmap, it helps to know how SRE differs from DevOps, since the two are constantly used interchangeably.
In short: DevOps tells you what to value (speed and reliability together). SRE tells you exactly how to achieve it, with numbers to prove it. Most job postings today blend the two, so don't worry about picking a "side"; focus on building skills that serve both.
One thing most guides skip: how long this actually takes. Here's a realistic breakdown so you can plan your SRE Learning Path without burning out.
| Stage | Focus Area | Realistic Timeframe |
| Beginner | Linux, networking, scripting, Git, cloud basics | 2–3 months |
| Intermediate | Containers, CI/CD, config management, monitoring | 3–4 months |
| Advanced | IaC, security, SLOs/SLIs, incident management | 4–6 months |
| Expert | Chaos engineering, capacity planning, system design, leadership | Ongoing, 1+ years on the job |
Most learners with consistent daily practice can be job-ready at the intermediate to advanced level within 8–12 months. Expert-level skills are built on the job, not in a course; no roadmap can compress that.
This is the heart of the SRE Roadmap: a level-by-level breakdown of exactly what to learn and why.
This is your foundation. At this stage, focus on getting comfortable with system administration, programming, and cloud platforms - nothing fancy yet.
Pro Tip: Don't try to memorize everything; get your hands dirty. Break a VM on purpose and fix it. Write a tiny script that automates one annoying manual task.
Once the basics are solid, move into the tools and practices that actually bring SRE to life day-to-day.
Pro Tip: Contribute to an open-source SRE tool or spin up a home lab on a free-tier cloud account. Nothing teaches faster than something breaking at 2 a.m. in your own sandbox.
By this stage of the SRE Roadmap 2026, you're not just fixing environments; you're designing and managing systems at scale. This is where reliability engineering really begins.
Pro Tip: Build (or simulate) an auto-scaling system, a failover setup, or a disaster-recovery drill. This is where real SRE instincts are formed.
This is where you go from a solid SRE to a strategic leader - not just executing tasks, but building a culture of reliability across teams.
Pro Tip: Experts often build internal tools their whole team ends up relying on. Think beyond tutorials; build something your company actually uses.
Before you go deeper into the technical SRE Roadmap 2026, get familiar with the principles that underpin the entire discipline. These aren't buzzwords - they're your guiding lights. For a more detailed breakdown of how these principles translate into day-to-day execution, see our complete guide to SRE Practices.
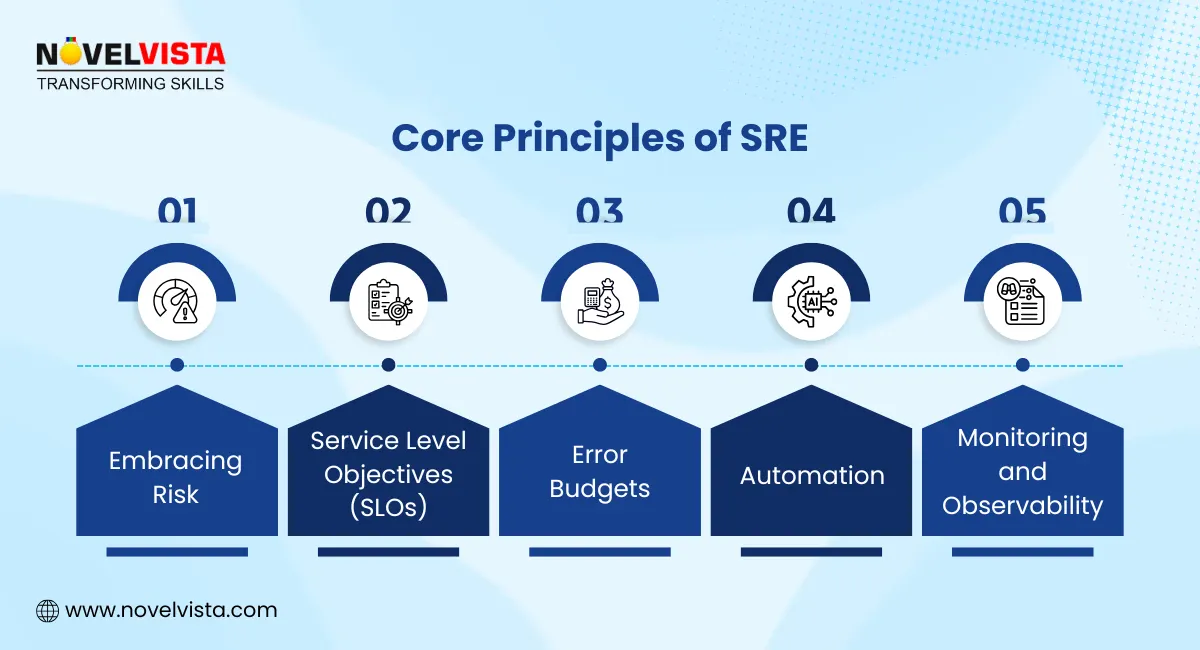
Systems will fail; it's inevitable. SRE encourages acknowledging that fact and designing with resilience in mind. It's risk management, not risk elimination.
Measurable targets for uptime, latency, or error rates. SLOs guide your efforts and set realistic reliability goals for your systems.
A genuinely clever concept. It lets you balance innovation and reliability: if your system hasn't used up its "error budget," you're free to ship new changes. If you've exceeded it, it's time to stabilize before shipping more.
Repetitive manual "work" should be automated wherever possible. Automating deployments, monitoring, and recovery frees up time for actual innovation.
Monitoring tells you when something is wrong. Observability tells you why. Tools like Prometheus, Grafana, and the ELK stack help SREs understand system health and behavior in real time.
These five principles will stay with you through every stage of the roadmap.
Most SRE guides list tools without context. Here's a quick-reference table mapped to what each category is actually for.
Category | Common Tools | What It's For |
| Monitoring & Observability | Prometheus, Grafana, Datadog, ELK Stack | Tracking metrics, logs, and traces in real time |
| Incident Management | PagerDuty, Opsgenie, Statuspage | Alerting, on-call rotation, and incident communication |
| Containerization & Orchestration | Docker, Kubernetes | Packaging and running applications consistently at scale |
| Infrastructure as Code | Terraform, CloudFormation, Pulumi | Provisioning infrastructure through version-controlled code |
| CI/CD | Jenkins, GitHub Actions, GitLab CI, ArgoCD | Automating build, test, and deployment pipelines |
| Configuration Management | Ansible, Puppet, Chef | Automating server configuration and maintenance |
| Chaos Engineering | Gremlin, Chaos Monkey, Litmus | Proactively testing system resilience |
You don't need to master every tool in this table; you need to understand why each category exists, then go deep on the specific tools your target companies actually use.
Certifications won't replace hands-on skill, but they do two useful things: they structure your learning, and they signal credibility to recruiters filtering resumes. A few worth considering as part of your SRE Roadmap:
NovelVista's SRE certification programs are designed to map directly onto this roadmap so you're not learning in a vacuum; you're building toward a recognized credential.
SRE remains one of the higher-paying specializations in tech, largely because so few engineers combine software skills with deep operational expertise. Compensation varies significantly by company size, location, and experience level — companies like Google are well known for paying SREs highly competitive packages compared to broader industry benchmarks. For a complete breakdown of roles, responsibilities, and how to break into the field, read our SRE Jobs and Career Guide.
A typical SRE path in terms of career progression looks like this:
Rather than chasing a number, focus on the fundamentals in this roadmap; compensation tends to follow demonstrated impact, not just job titles.
This is the one area competitor guides gloss over, and it's the biggest shift in the field right now. AI isn't replacing SRE; it's changing what "automation" means at every level of the roadmap.
The takeaway for anyone following this: don't treat AI tooling as optional at the Advanced or Expert level. The SREs who thrive in 2026 are the ones who know how to supervise and validate AI-driven systems, not just build automation scripts by hand.
A few patterns show up again and again with people following an SRE Learning Path for the first time:
Avoiding these five mistakes alone will put you ahead of a large share of candidates following the same roadmap.
If you're just starting, don't get overwhelmed. The SRE Roadmap may look long, but every expert was once a beginner.
Becoming a Site Reliability Engineer in 2026 isn't just a career choice; it's a smart investment in your future.
The digital world runs on reliability, speed, and security. Whether you're fresh out of college or transitioning from a development or sysadmin role, this SRE Roadmap gives you a clear, sequenced path to follow instead of a pile of scattered tutorials.
As you progress through your learning journey, pursuing an SRE Foundation Certification can help you build a strong understanding of SRE principles. In contrast, an SRE Practitioner Certification can help you develop more advanced, practical skills.
With structured learning, the right mindset, and support from experienced mentors like those at NovelVista, your transformation from learner to leader isn't a distant dream - it can be your next career move.
Yes, SREs write code to automate infrastructure, monitoring, and reliability tasks. While not purely software engineers, coding in Python, Go, or similar languages is essential to improve system performance and reduce manual work.
Most SREs hold degrees in Computer Science, IT, or related fields. However, degrees aren’t always mandatory. Hands-on skills matter more. Completing certifications from Accredited Training Organizations (ATOs) can strongly boost your chances of becoming an SRE.
SRE can be challenging because it combines software engineering with operations, requiring problem-solving under pressure. However, it’s rewarding, offering strong career growth for those who enjoy automation, reliability, and building scalable systems.
AI will automate repetitive tasks in SRE, but it won’t replace the role. Instead, SREs will use AI to enhance reliability engineering, focus on innovation, and manage complex systems that automation alone can’t handle.
Google pays highly competitive salaries to SREs, often among the best in the industry. Exact figures vary by role, experience, and location, but Google is widely recognized for offering attractive compensation and benefits.
Most learners reach job-ready. Intermediate/advanced skills in 8–12 months of consistent study and hands-on practice. Expert-level skills - chaos engineering, capacity planning, and large-scale system design - are typically built over a year or more on the job.
Yes. As more organizations run mission-critical workloads on cloud-native infrastructure, the need for engineers who can prevent outages - not just respond to them - continues to grow across startups, enterprises, and FAANG-scale companies alike.
Author Details
Course Related To This blog
SRE Foundation and Practitioner Combo
SRE Certification Course
SRE Foundation and SRE Practitioner combo
SRE Practitioner
SRE Foundation
Confused About Certification?
Get Free Consultation Call
Stay ahead of the curve by tapping into the latest emerging trends and transforming your subscription into a powerful resource. Maximize every feature, unlock exclusive benefits, and ensure you're always one step ahead in your journey to success.